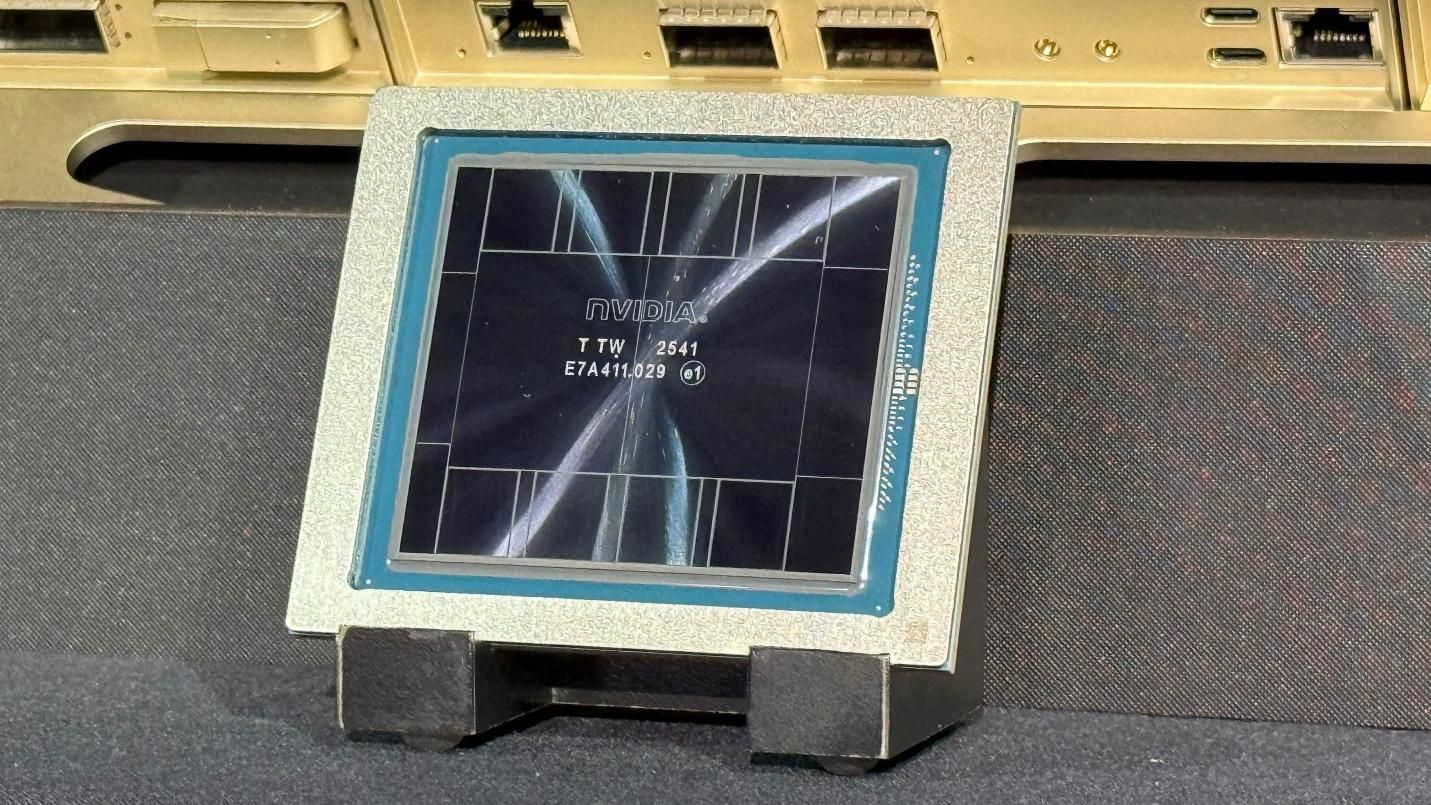
Nvidia details Rubin architectural optimizations for inference – improvements target better performance and efficiency from the GPU to the rack

MoE expert weights can be distributed across GPUs in order to efficiently utilize limited per-GPU HBM capacity. Nvidia says that Rubin’s TMA has been improved to deal with the challenges of managing the growing numbers o…

Intel and AMD sign long-term server CPU deals with Chinese customers as prices jump over 40%, report claims — agreements purportedly guarantee purchase volumes

Some customers have discussed commitments running two years or longer, one of the people told Reuters , with the deals covering unit volumes only, which leaves Chinese cloud providers and internet companies fully exposed…

Fortinet becomes Intel 4’s first foundry customer, following firewall ASIC deal — CEO Lip-Bu Tan’s promised foundry wins begin to surface, but on a mature node

Meteor Lake is aging out of Intel’s lineup as 18A-based Panther Lake ramps through 2026, which leaves open the question of what fills Intel 4 capacity next. A multi-generation firewall ASIC program is a reasonable answer…

Z.ai powers up a 1-gigawatt AI data center built entirely on Chinese chips, report claims — GLM developer now runs multiple 10,000-chip clusters with zero Nvidi

The source didn’t name the chip supplier, but Z.ai’s recent training history points to Huawei. The company released GLM-5.2 in June , an open-weight model purportedly trained entirely on Huawei Ascend accelerators with n…

Anthropic hit with largest-ever $1.5 billion penalty in copyright lawsuit — court says training AI on published material is fair use, but startup’s pirated libr

Jowi Morales is a tech enthusiast with years of experience working in the industry. He\u2019s been writing with several tech publications since 2021, where he\u2019s been interested in tech hardware and consumer electron…