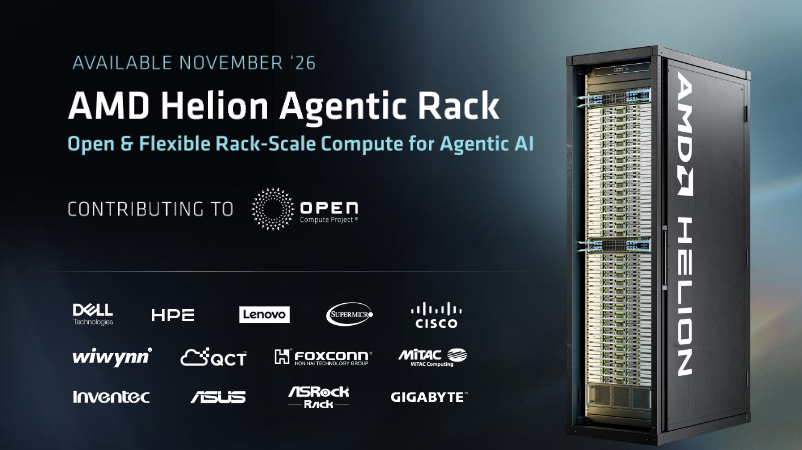
Presumably, this is the model AMD is aiming at with Helion as hyperscalers build out CPU capacity on the back of agentic AI. However, the design is flexible, supporting up to 16 MI350P GPUs and 102 Tbps of networking, though at the cost of CPU capacity. This hybrid configuration is targeted at enterprises, says AMD, giving them an all-in-one rack for data management, networking, and AI usage.
AMD says the Helion rack will be available starting in the first half of 2027, likely riding the wave of Zen 6 deployments that are expected to start ramping up later this year.
(Image credit: AMD) (Image credit: AMD) (Image credit: AMD) (Image credit: AMD) (Image credit: AMD) (Image credit: AMD) (Image credit: AMD) (Image credit: AMD) (Image credit: AMD) Image 1 of 9 View Original
Follow Tom's Hardware on Google News , or add us as a preferred source , to get our latest news, analysis, & reviews in your feeds.
Jake Roach Social Links Navigation Senior Analyst, CPUs Jake Roach is the Senior CPU Analyst at Tom’s Hardware, writing reviews, news, and features about the latest consumer and workstation processors.
jp7189 "OpenU trays, which are 21mm wide and 48mm tall" 21mm ? Now that's dense! In reality, those trays are actually 537mm Reply
JakeRoach jp7189 said: "OpenU trays, which are 21mm wide and 48mm tall" 21mm ? Now that's dense! In reality, those trays are actually 537mm Thanks for catching that! Inches, not mm. I've corrected the article. Reply
DS426 Ouch, AMD put that OpenAI card in their presentation talking about 10,000 agents being used to solve Navier-Stokes? That one is kind of… controversial to say the least, lol. Reply
alan.campbell99 DS426 said: Ouch, AMD put that OpenAI card in their presentation talking about 10,000 agents being used to solve Navier-Stokes? That one is kind of… controversial to say the least, lol. Aye, something about them burning that much resources to do this as well as effectively stealing the researcher's work. That they would surrender credit to one of the researchers if he cut loose the other guy because he happened to be an Anthropic employee . Reply
Stomx By the way people think that 32 000 of processors will do your prompt 32 000 faster (so called "strong scaling" in multiprocessing) . In reality it depends. Mostly such 32 000 processors servers will be used to serve roughly saying 32 000 people /tasks at the same time (this is "weak scaling") . And specifically when you send your request over internet and Google AI get it, you will be served typically by just one of these processors because other processors will be busy serving other requests. Try to ask Google something serious during day time and the rush hours – noticed that hallucination rate increases ? Yesterday during the whole day time I was getting almost 100% hallucination rate ! At night time it always worked not that bad So if you buy just one such chip and do your stuff locally, you will not lose anything in speed and very rarely will need multiprocessing with thousands cores because your AMD processor already has up to 256 cores. Also typically majority of problems are not linearly parallelizable with the number of cores. I permanently see that adding more than 200 cores gives little advantage and say 8 processors only deliver the performance of 3 of them in strong scaling Reply
bit_user Stomx said: And specifically when you send your request over internet and Google AI get it, you will be served typically by just one of these processors because other processors will be busy serving other requests. Meta's new AI agents reportedly use 2-core VMs with 8 GB of RAM: https://www.tomshardware.com/pc-components/cpus/meta-muse-runs-agents-on-amd-epyc-turin-hosts-with-two-cores-and-8gb-of-memory-ai-agent-can-pass-terminal-commands-to-ubuntu-host-system OpenAI's Dots agents seem to run on 9-core VMs: https://www.tomshardware.com/tech-industry/artificial-intelligence/geekbench-7-results-suggest-openais-dots-agent-runs-on-nine-core-amd-epyc-vms-with-nearly-10gb-of-memory-newest-runs-score-about-six-times-meta-muse-in-multi-core Stomx said: Try to ask Google something serious during day time and the rush hours – noticed that hallucination rate increases ? Yesterday during the whole day time I was getting almost 100% hallucination rate ! At night time it always worked not that bad That's interesting, but not related to CPU cores. They use either Tensor processors or Nvidia GPUs for inferencing, not CPUs. Stomx said: So if you buy just one such chip and do your stuff locally, you will not lose anything in speed and very rarely will need multiprocessing with thousands cores because your AMD processor already has up to 256 cores. Sure, why not? I was meaning to wire up the house with 3-phase power, anyhow. ; ) Stomx said: Also typically majority of problems are not linearly parallelizable with the number of cores. What you can do is have multiple agents running simultaneously . Either teaming up on a single problem, or you dispatch them to work on different problems. Or, you have them compete on the same problem, which is redundant but might get you a better solution. Each of those agents could have its own dual-vCPU VM. Reply
usertests Stomx said: Try to ask Google something serious during day time and the rush hours – noticed that hallucination rate increases ? Yesterday during the whole day time I was getting almost 100% hallucination rate ! At night time it always worked not that bad Aren't they using the same 3.5 Flash-Lite model for any particular search? What lever would they have to pull to lower the quality, limit the amount of reasoning loops or something? Reply
Stomx usertests said: Aren't they using the same 3.5 Flash-Lite model for any particular search? What lever would they have to pull to lower the quality, limit the amount of reasoning loops or something? Yes, most probably during rush hours they decrease number of parallel GPU/TPUs and reasoning depth. I asked and AI told me this was "Google 3.8 family AI". Flash is not as bad in Intelligence index, not far from top in AA Omniscience index 47 positive vs 17 hallucinations Reply
bit_user Stomx said: I asked and AI told me this was "Google 3.8 family AI". Assuming it wasn't hallucinating! ; ) Reply
Key considerations
- Investor positioning can change fast
- Volatility remains possible near catalysts
- Macro rates and liquidity can dominate flows
Reference reading
- https://www.tomshardware.com/pc-components/cpus/SPONSORED_LINK_URL
- https://www.tomshardware.com/pc-components/cpus/amd-debuts-helion-reference-design-for-agentic-ai-servers-with-up-to-32-768-zen-6-venice-cores-rack-design-ships-next-year-in-cpu-only-and-all-in-one-configurations#main
- https://www.tomshardware.com/membership
- Redditor unknowingly buys stolen rental PC, and it gets remotely blocked by rental firm
- Developer uses Claude to enable Xbox Cloud Gaming on jailbroken PS5s
- Epic Games reportedly delays Disney shooter title so it can pivot to AI coding
- Fall Into 25 New Games on GeForce NOW This October
- All Systems Go: Global PC App Ecosystem Ready for NVIDIA RTX Spark
Informational only. No financial advice. Do your own research.