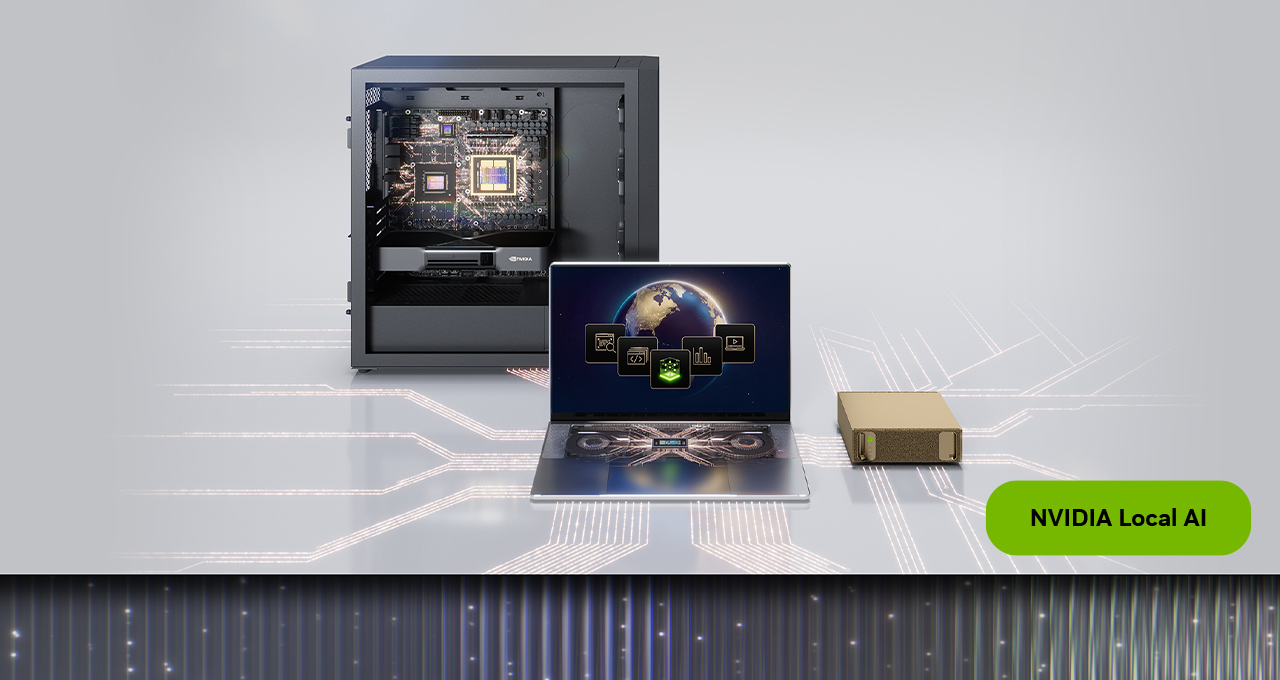
NVIDIA Sync Model Launcher will also be available later this month. It simplifies access to local AI on a single DGX Spark or a cluster. With a few clicks, Model Launcher downloads a model and container suited to the configuration and connects the model to OpenCode. It automatically loads DGX Spark Skills for troubleshooting, device maintenance, access to official documentation and other workflow guidance.
The October DGX Spark software update brings a new Wi-Fi Assistant that lets users switch networks when DGX Spark is running in appliance mode. Plus, DGX Spark Skills provide workflow-focused guidance in troubleshooting and device maintenance directly into NVIDIA Sync via OpenCode.
DGX Spark systems are available directly from Acer , ASUS , Dell Technologies , GIGABYTE , HP , Lenovo, MSI and NVIDIA.
For larger teams, DGX Station offers 748GB of coherent memory and up to 20 petaflops of AI performance, enabling developers to run advanced models like GLM 5.3 and serve 30+ users at speeds comparable to those provided by cloud models. Adding scale, NVIDIA Sync now supports DGX Station, simplifying connections between two Linux-based systems.
New integrations with Absolute Security , Splunk by Cisco , Fleet Device Managemen t , Microsoft Intune , Perforce Puppet , Progress Software Chef and Tanium let IT teams manage DGX Station systems through enterprise setup, management and conformity processes, helping accelerate approvals and reduce deployment risk while minimizing time to first token.
With the upcoming Windows-based systems, developers can build workflows that harness professional applications, run on NVIDIA RTX PRO GPUs and operate from agents that run their large language models (LLMs) on NVIDIA GB300 systems — all in one machine.
DGX Station for Windows , expected from system manufacturer partners in December, extends local AI into the applications and operating environment enterprises already use. Engineers can run local models and agents in Windows-native software with access to AI models, tools and agents on the same system.
DGX Station for Windows will feature support for manufacturing applications from nTop , Dassault Systèmes , Keysight Technologies , MathWorks , Rockwell Automation , Siemens , Synopsys , Unity and Altera for AI-guided design, simulation, validation and engineering automation. Users will be able to run agents using Hermes Agent , Perplexity or Aible on premises for agentic control in enterprise environments.
The same local, controlled computing model extends to robotics. DGX Station gives robotics teams dedicated compute for post-training, simulation and evaluation, shortening iteration cycles without waiting for shared infrastructure.
NVIDIA released three open source reference workflows that bring GPT-6 Astra, NVIDIA Isaac Lab, Isaac Lab-Arena and Cosmos to NVIDIA DGX Station. Developers can use them to refine GR00T 1.7 models with reinforcement learning, train dexterous manipulation skills and post-train Cosmos world models for synthetic data generation.
NVIDIA Cloud Functions is coming in early access to Linux-based DGX Station. Teams can register local model endpoints in a shared catalog and access them through one OpenAI-compatible entry point.
Developers can upgrade the model behind an endpoint without changing application code, while teammates can use shared models without direct machine access. This turns a DGX Station into a locally controlled inference service for a team.
DGX Station brings local iteration to AI factory development. On the show floor at GTC Berlin, NVIDIA is previewing DSX OS running on DGX Station to simulate AI factory operations before full infrastructure is available. Another demo will showcase DGX Station systems powering a local token factory for more than 30 software developers.
DGX Station systems are shipping today from ASUS , Dell Technologies , GIGABYTE , HP , MSI , Supermicro and Exxact . DGX Station for Windows systems are expected to begin shipping later this year from ASUS , Dell Technologies , GIGABYTE , HP , MSI and Supermicro .
Today, frontier AI lab Recursive Superintelligence released Recursive Flint , a local LLM built for fast, accurate coding. A 40-billion-parameter mixture-of-experts model with 2.5 billion active parameters, Recursive Flint delivers fast inference and performs well in agentic coding benchmarks like S WE-Bench Pro v2, Terminal-Bench 2.1 and SWE-bench verified.
Recursive Flint was built using Recursive’s Eureka Machine, a system for large-scale automated AI research. It automates the full research loop: proposes ideas, implements them, runs experiments to validate ideas and uses the results to decide what to try next — creating specialized kernels that boosted Flint’s generation speed on RTX Spark by 55% without changing the model’s weights.
Developers can download the open weights on Hugging Face under the Apache 2.0 license and run the model on RTX Spark and DGX Spark systems, as well as GeForce RTX and RTX PRO GPUs. Developers can also post-train the model with NeMo Automodel for supervised fine-tuning and low-rank adaptation, or LoRa, as well as NeMo RL for group relative policy optimization.
NVIDIA is also adding day-zero model support for NVIDIA Nemotron Bolt E4B 4B, GLM, DeepSeek, Qwen, MiniMax, Liquid AI’s LFM2.5-24B-A2B, plus the FLUX.3 Klein diffusion model.
Nemotron Bolt E4B 4GB packs natural conversation and multi-turn agentic skills into as little as 4GB of memory, powering fast local voice assistants, interactive game characters and embedded interfaces on NVIDIA GeForce RTX GPUs, NVIDIA Jetson devices, and RTX and DGX Spark. Bolt E4B 4GB releases on Friday, Oct. 23.
Black Forest Labs’ FLUX 3 Image Klein is a 5.6-billion-parameter open weights image model for generation and editing. NVIDIA-optimized builds let it run on GeForce RTX GPUs with as little as 8GB of VRAM and create a 1-megapixel image in about four seconds on an RTX 5090 GPU.
MiniMax M3.1 Flash is a new open model built for NVIDIA DGX Station and DGX Spark, bringing long-context AI to the desktop. Liquid AI’s LFM2.5-24B-A2B is an open weights reasoning model that activates just 2 billion of its 24 billion parameters per token, making it fast enough to run private, tool-calling AI agents directly on PCs.
Plus, NVIDIA has released a new collection of model checkpoints optimized for RAM efficiency on local AI hardware, enabling frontier-class open models to run with sufficient memory left over for KV cache. Each checkpoint is quantized while staying close to full-precision accuracy, starting with Qwen3.8-Flash-Next-FP4-Local on a single DGX Spark 128GB or RTX PRO 6000 and GLM-5.3-Flash-FP4-Local on two systems.
Developers can post-train on day zero with NeMo AutoModel on both DGX Spark and RTX Spark, with example recipes for Nemotron Bolt E4B , Flux 3 Image Klein and more.
NVIDIA continues to work with the llama.cpp and vLLM open source communities to accelerate agentic workloads on local hardware.
In llama.cpp, new speculative decoding support with MTP for Qwen 3.8 Flash Next makes end-to-end agentic tasks up to 1.4x faster on NVIDIA RTX PRO 6000 Blackwell.
In vLLM, faster speculative decoding and new FlashInfer prefill kernels for Qwen’s linear-attention layers make agentic tasks with Qwen3.8 27B up to 1.3x faster on DGX Spark. On DGX Station, GLM 5.3 Flash gets up to 1.2x higher throughput.
Check out NVIDIA’s local AI inference recipes to try these latest optimizations.
See notice regarding software product information.
Key considerations
- Investor positioning can change fast
- Volatility remains possible near catalysts
- Macro rates and liquidity can dominate flows
Reference reading
- https://blogs.nvidia.com/blog/local-ai-gtc-rtx-dgx-spark-station-sync/#primary
- https://blogs.nvidia.com/blog/author/gdelgado/
- https://blogs.nvidia.com/blog/local-ai-gtc-rtx-dgx-spark-station-sync/#disqus_thread
- European Leaders Turn to NVIDIA Vera CPUs to Build Local Infrastructure
- China’s tech giants drop $35 billion on export-compliant Nvidia RTX Pro 5500 workstation GPU orders to power AI ambitions, according to reports
- FADU puts the filesystem inside the SSD's flash to bypass host CPUs
- F-22 Raptor pilot successfully demonstrates command of 'wingman' fighter drone in simulated combat
- Modern software is built on the backs of low-paid maintainers, opening the door to potential threats
Informational only. No financial advice. Do your own research.