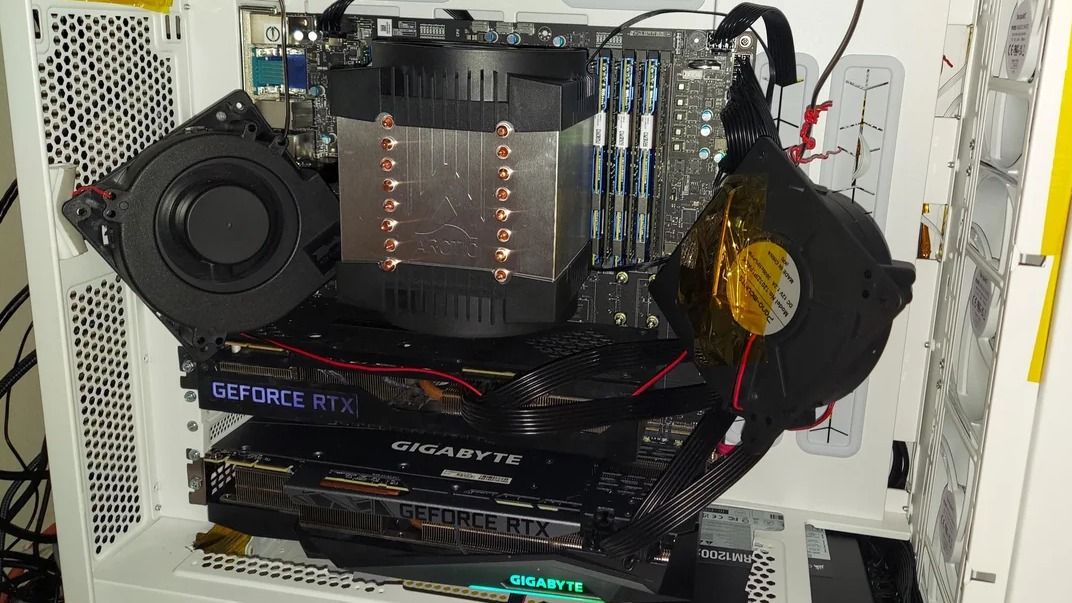
The speed that came with the GPUs is within the range of what the builder expected, guessing “somewhere between 2 and 4 tokens per second” in a prediction from the original build thread. The GPU install had to wait, in part, for modifications to the case, which required cutting out some of the metal and relocating the PSU to make room for the GPUs and their cooling. Cooling remains a huge issue, with “the improved throughput [not changing] the original thermal warning,” and the two 12W blower fans for the Optane DIMMs are kept in place. Add in dual 350W-class GPUs , and the changes are understandable.
Things won’t stop here, as more optimizations are possible, including “customized quantization,” which may be similar to the techniques used by lawyer Nick Mermiges . Quantization selected per tensor or layer, or by where the data lives, might reduce bandwidth and capacity pressures for the slower tiers; the setup “might be faster yet.” Speed, or tokens per second alone, is not enough, and output quality must be taken into consideration in any future plan.
Follow Tom’s Hardware on Google News , or add us as a preferred source , to get our latest news, analysis, & reviews in your feeds.
Shane Downing Social Links Navigation Contributing Writer Shane Downing is a Contributing Writer for Tom’s Hardware, covering consumer storage, PC hardware, and AI.
Key considerations
- Investor positioning can change fast
- Volatility remains possible near catalysts
- Macro rates and liquidity can dominate flows
Reference reading
- https://www.tomshardware.com/tech-industry/artificial-intelligence/SPONSORED_LINK_URL
- https://www.tomshardware.com/tech-industry/artificial-intelligence/homelabbers-second-gen-optane-build-runs-2-8-trillion-parameter-kimi-k3-at-3-11-tokens-per-second-after-adding-two-rtx-3090s-moving-nearly-half-the-model-into-a-ram-drive-boosted-performance-by-41-percent#main
- https://futureplc.com/terms-conditions/
- Phison details SSD with a built-in NPU and 64GB of memory that supports AI frameworks on the drive
- Score a huge 49% saving on a 2TB Samsung 9100 Pro SSD while you can
- How the World’s Most Advanced AI Infrastructure Supply Chain Invents the Future
- SanDisk 512GB MicroSD Express deal slashes Switch 2 storage by 24% in Amazon Black Friday offer — price hits under $100 amid storage squeeze
- Elon Musk’s SpaceXAI suffers chemical spill at Mississippi AI data center
Informational only. No financial advice. Do your own research.