Hot Chips 2026: Cerebras lays out the future of wafer-scale AI — Nexus system architecture triples rack-scale performance, CS-6 wafer to incorporate stacked DRA

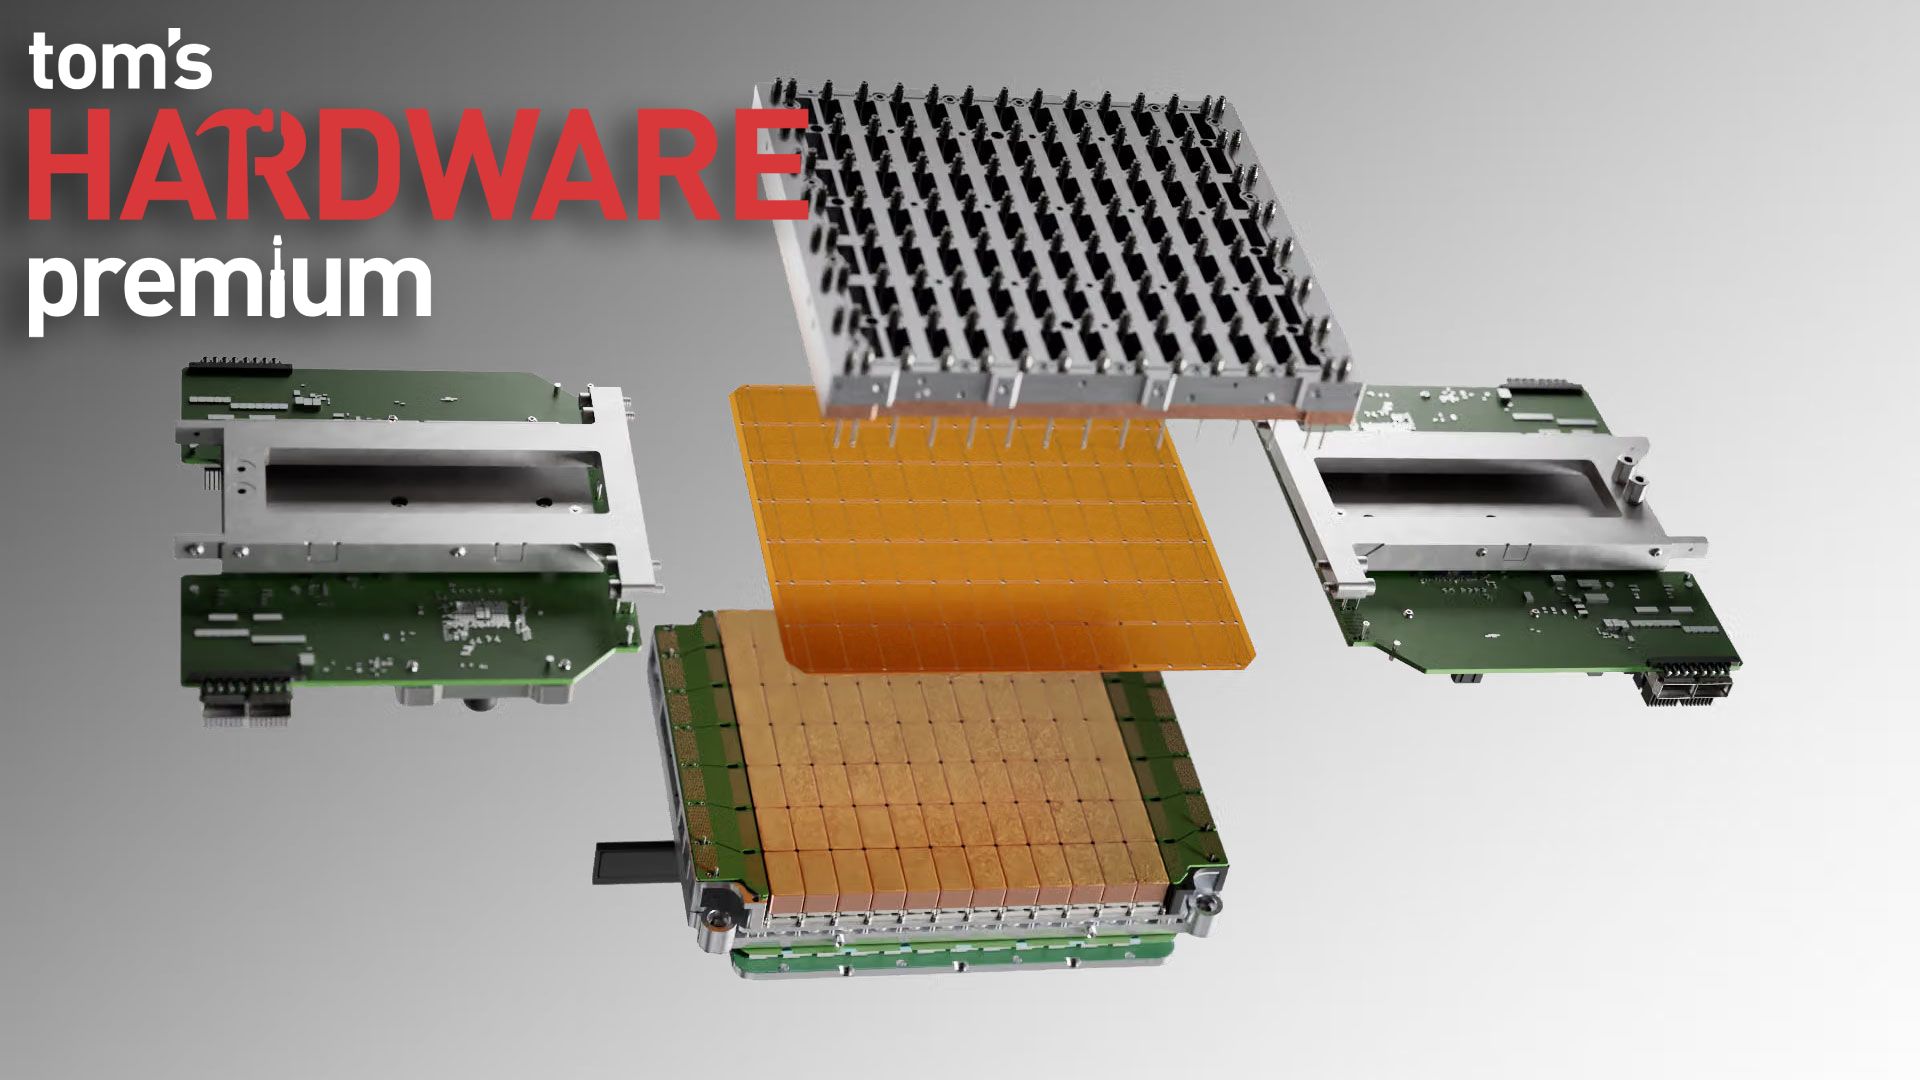
Mounting the wafer-scale engines vertically in the backpack modules lets Cerebras do away with a PCB or substrate for the wafer to handle all its supporting infrastructure. Instead, the backpack connects the large copper…
Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark — LP30-based rack already in production, company s

A Rubin GPU carries 288GB of HBM4 , roughly 576 times the memory of a single LP30, so a 31-billion-parameter model at FP8 needs on the order of 62 LPUs to hold its weights, and a large mixture-of-experts model runs into …

Hot Chips 2026: OpenAI’s Jalapeño AI ASIC unpacked — accelerator developed using AI achieves efficiency and throughput gains against power-hungry Blackwell

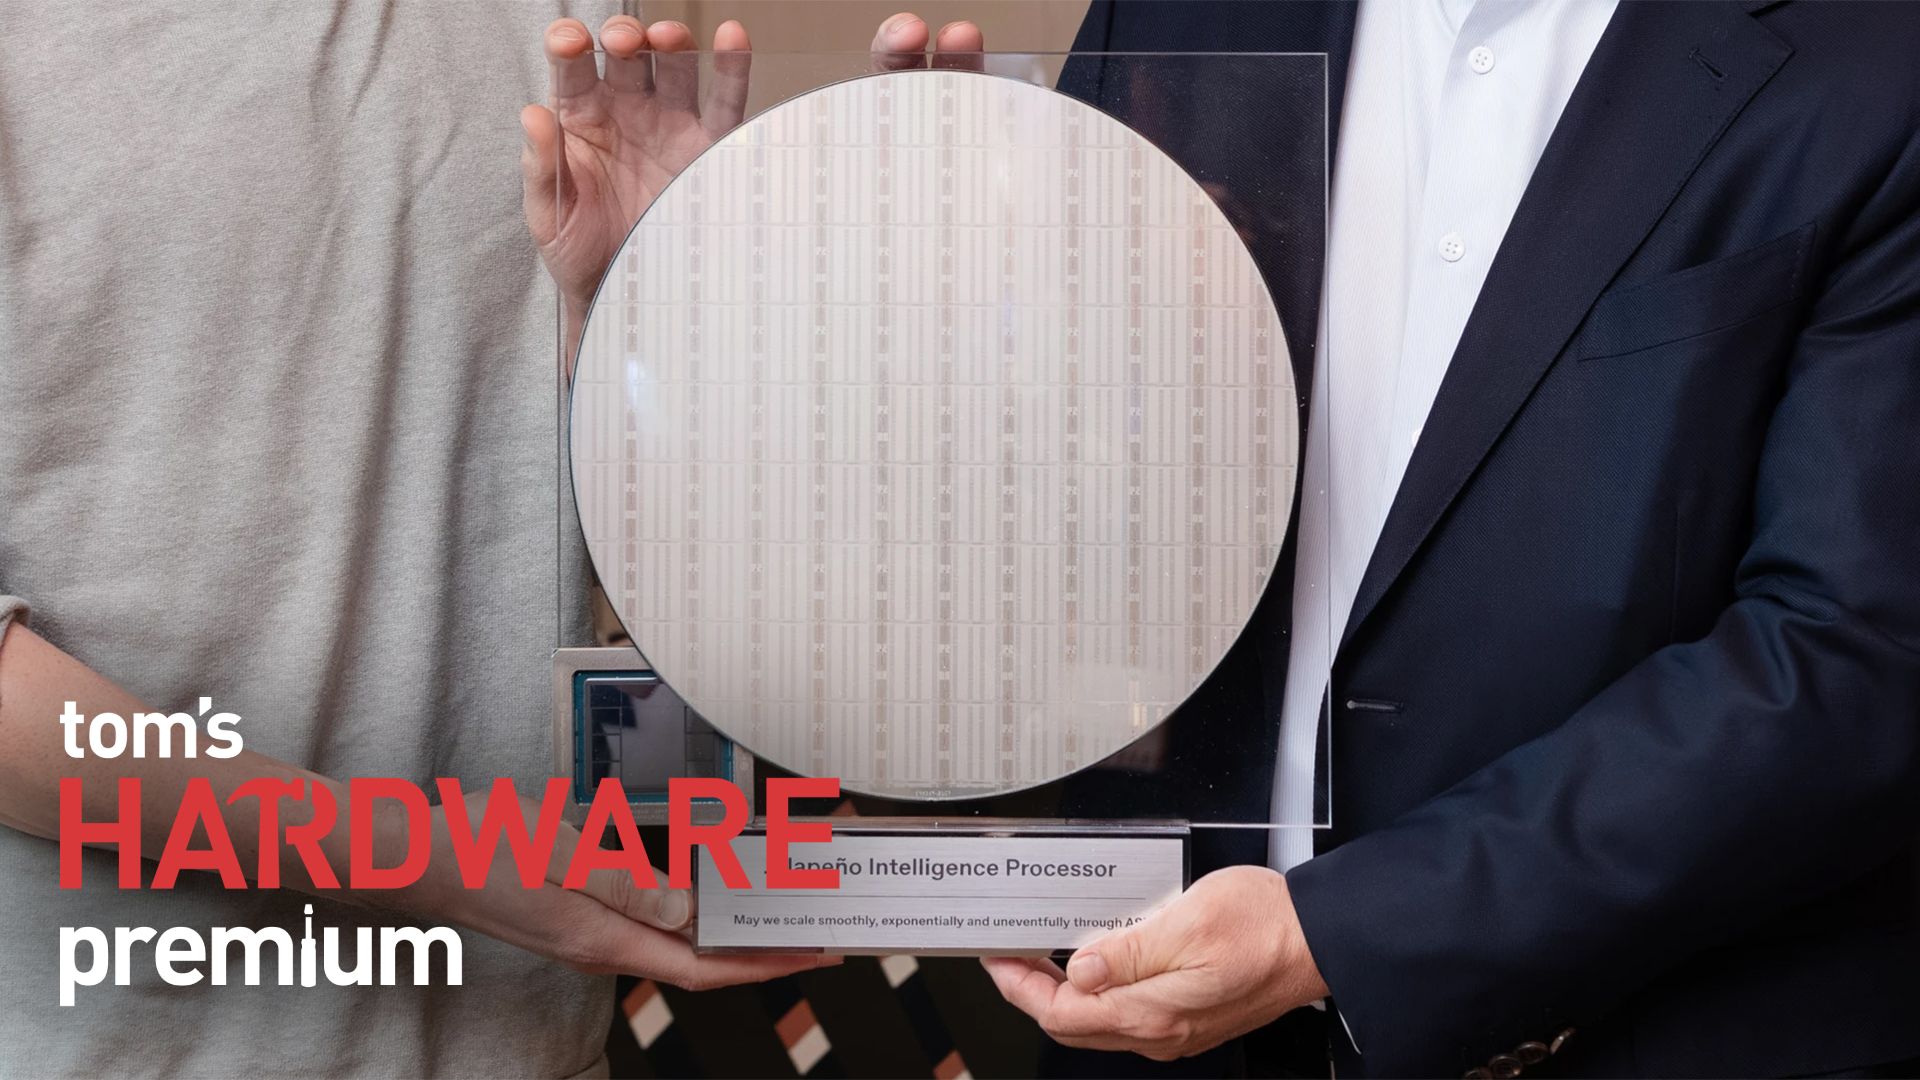
To explain how it works, let us compare OpenAI’s and Nvidia’s approaches. Nvidia’s standard system-level decomposition is primarily two phases: prefill and decode. Prefill is generally compute-bound (which is why Nvidia …

Hot Chips 2026: Cerebras lays out the future of wafer-scale AI — Nexus system architecture triples rack-scale performance, CS-6 wafer to incorporate stacked DRA

Mounting the wafer-scale engines vertically in the backpack modules lets Cerebras do away with a PCB or substrate for the wafer to handle all its supporting infrastructure. Instead, the backpack connects the large copper…
Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark — LP30-based rack already in production, company s

A Rubin GPU carries 288GB of HBM4 , roughly 576 times the memory of a single LP30, so a 31-billion-parameter model at FP8 needs on the order of 62 LPUs to hold its weights, and a large mixture-of-experts model runs into …

Hot Chips 2026: Nvidia breaks down 88-core Vera CPU — spatial multithreading benchmarked, 1.2 TB/s SOCAMM2 memory, agentic workloads detailed, and more

Nvidia’s slide does a good job illustrating, but it’s worth noting the difference compared to traditional SMT nonetheless. With traditional SMT, resources are time-sliced between threads, leading to gaps between BP and d…

Hot Chips 2026: Arm details AGI server CPU with two 70-core N3P chiplets — touts 2 TB/s UCIe fabric link and 12-channel memory controller

The important point is that CMN-S3 is not just an internal CPU mesh, as Arm designed the coherent system to extend outside of the die to extend coherency beyond the die and the socket. The approach is conceptually closer…

Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark — LP30-based rack already in production, company s

An FPGA bridges the synchronous LPU domain and the asynchronous world of host I/O and GPU hand-offs, and Nvidia’s Dynamo runtime, together with an LPU extension to CUDA, orchestrates the split. The company put the gains …