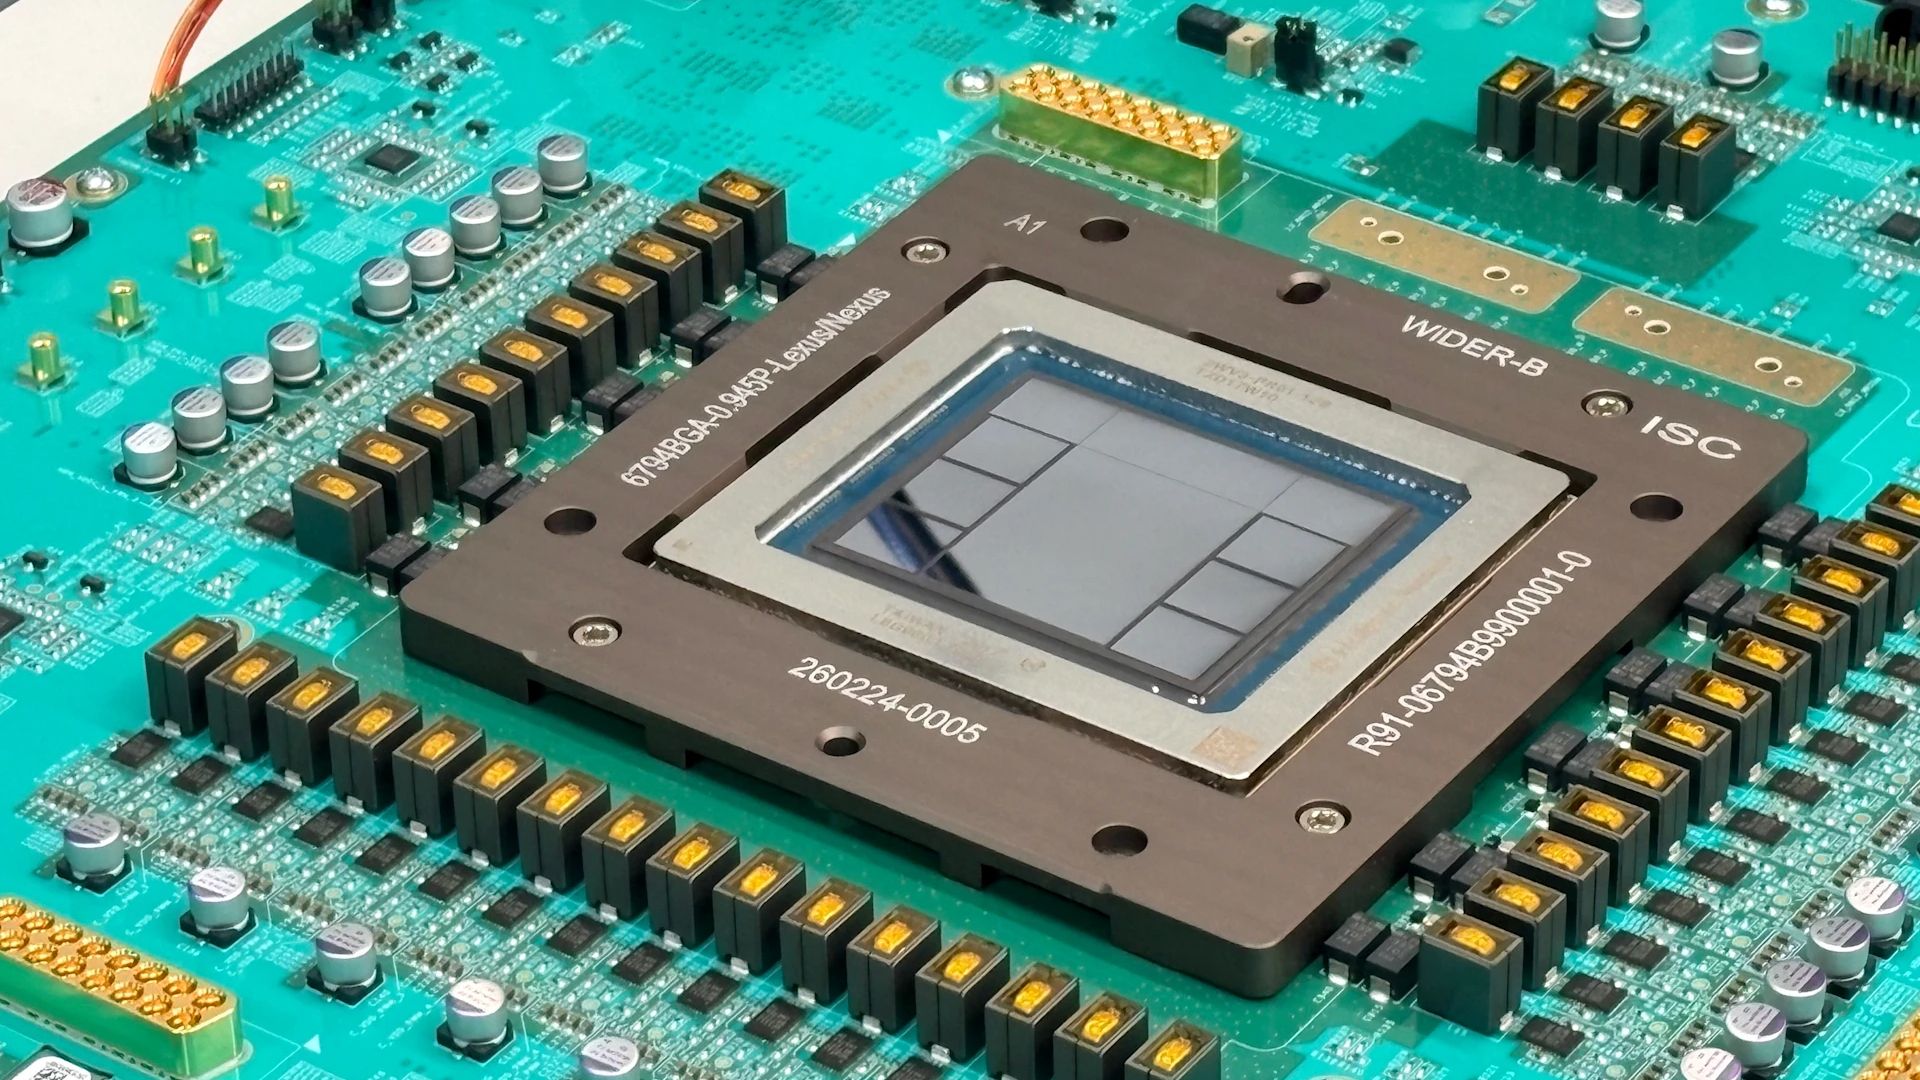
OpenAI’s custom Jalapeno AI inference ASIC is for OpenAI’s internal use, but company leaves the door open to broader rollout
When you purchase through links on our site, we may earn an affiliate commission. Here’s how it works .
When you purchase through links on our site, we may earn an affiliate commission. Here’s how it works .
When you purchase through links on our site, we may earn an affiliate commission. Here’s how it works .
When you purchase through links on our site, we may earn an affiliate commission. Here’s how it works .
Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark
Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark
Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark
To explain how it works, let us compare OpenAI’s and Nvidia’s approaches. Nvidia’s standard system-level decomposition is primarily two phases: prefill and decode. Prefill is generally compute-bound (which is why Nvidia …
To explain how it works, let us compare OpenAI’s and Nvidia’s approaches. Nvidia’s standard system-level decomposition is primarily two phases: prefill and decode. Prefill is generally compute-bound (which is why Nvidia …
To explain how it works, let us compare OpenAI’s and Nvidia’s approaches. Nvidia’s standard system-level decomposition is primarily two phases: prefill and decode. Prefill is generally compute-bound (which is why Nvidia …