Exploring Apple Silicon’s local AI performance with the Mac Studio and M4 Max — M4 Max beats GB10 and Strix Halo in decode throughput, but memory bandwidth isn’

As the Senior Analyst, Graphics at Tom’s Hardware, Jeff Kampman covers everything that has to do with graphics cards, gaming performance, and more. From integrated graphics processors to discrete graphics cards to the hy…

Exploring Apple Silicon’s local AI performance with the Mac Studio and M4 Max — M4 Max beats GB10 and Strix Halo in decode throughput, but memory bandwidth isn’

As the Senior Analyst, Graphics at Tom’s Hardware, Jeff Kampman covers everything that has to do with graphics cards, gaming performance, and more. From integrated graphics processors to discrete graphics cards to the hy…

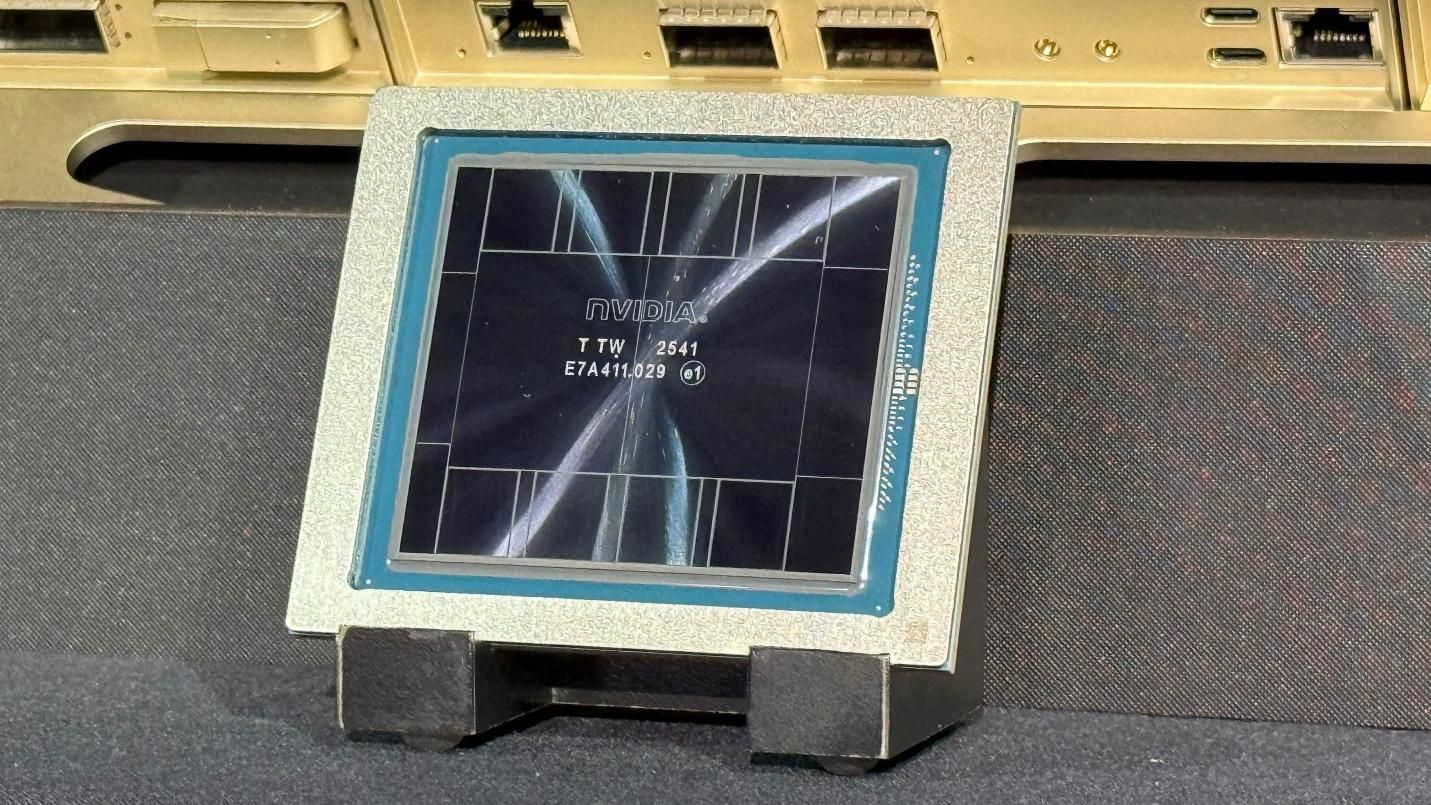
Nvidia details Rubin architectural optimizations for inference – improvements target better performance and efficiency from the GPU to the rack

MoE expert weights can be distributed across GPUs in order to efficiently utilize limited per-GPU HBM capacity. Nvidia says that Rubin’s TMA has been improved to deal with the challenges of managing the growing numbers o…