Nvidia details Rubin architectural optimizations for inference – improvements target better performance and efficiency from the GPU to the rack

MoE expert weights can be distributed across GPUs in order to efficiently utilize limited per-GPU HBM capacity. Nvidia says that Rubin’s TMA has been improved to deal with the challenges of managing the growing numbers o…

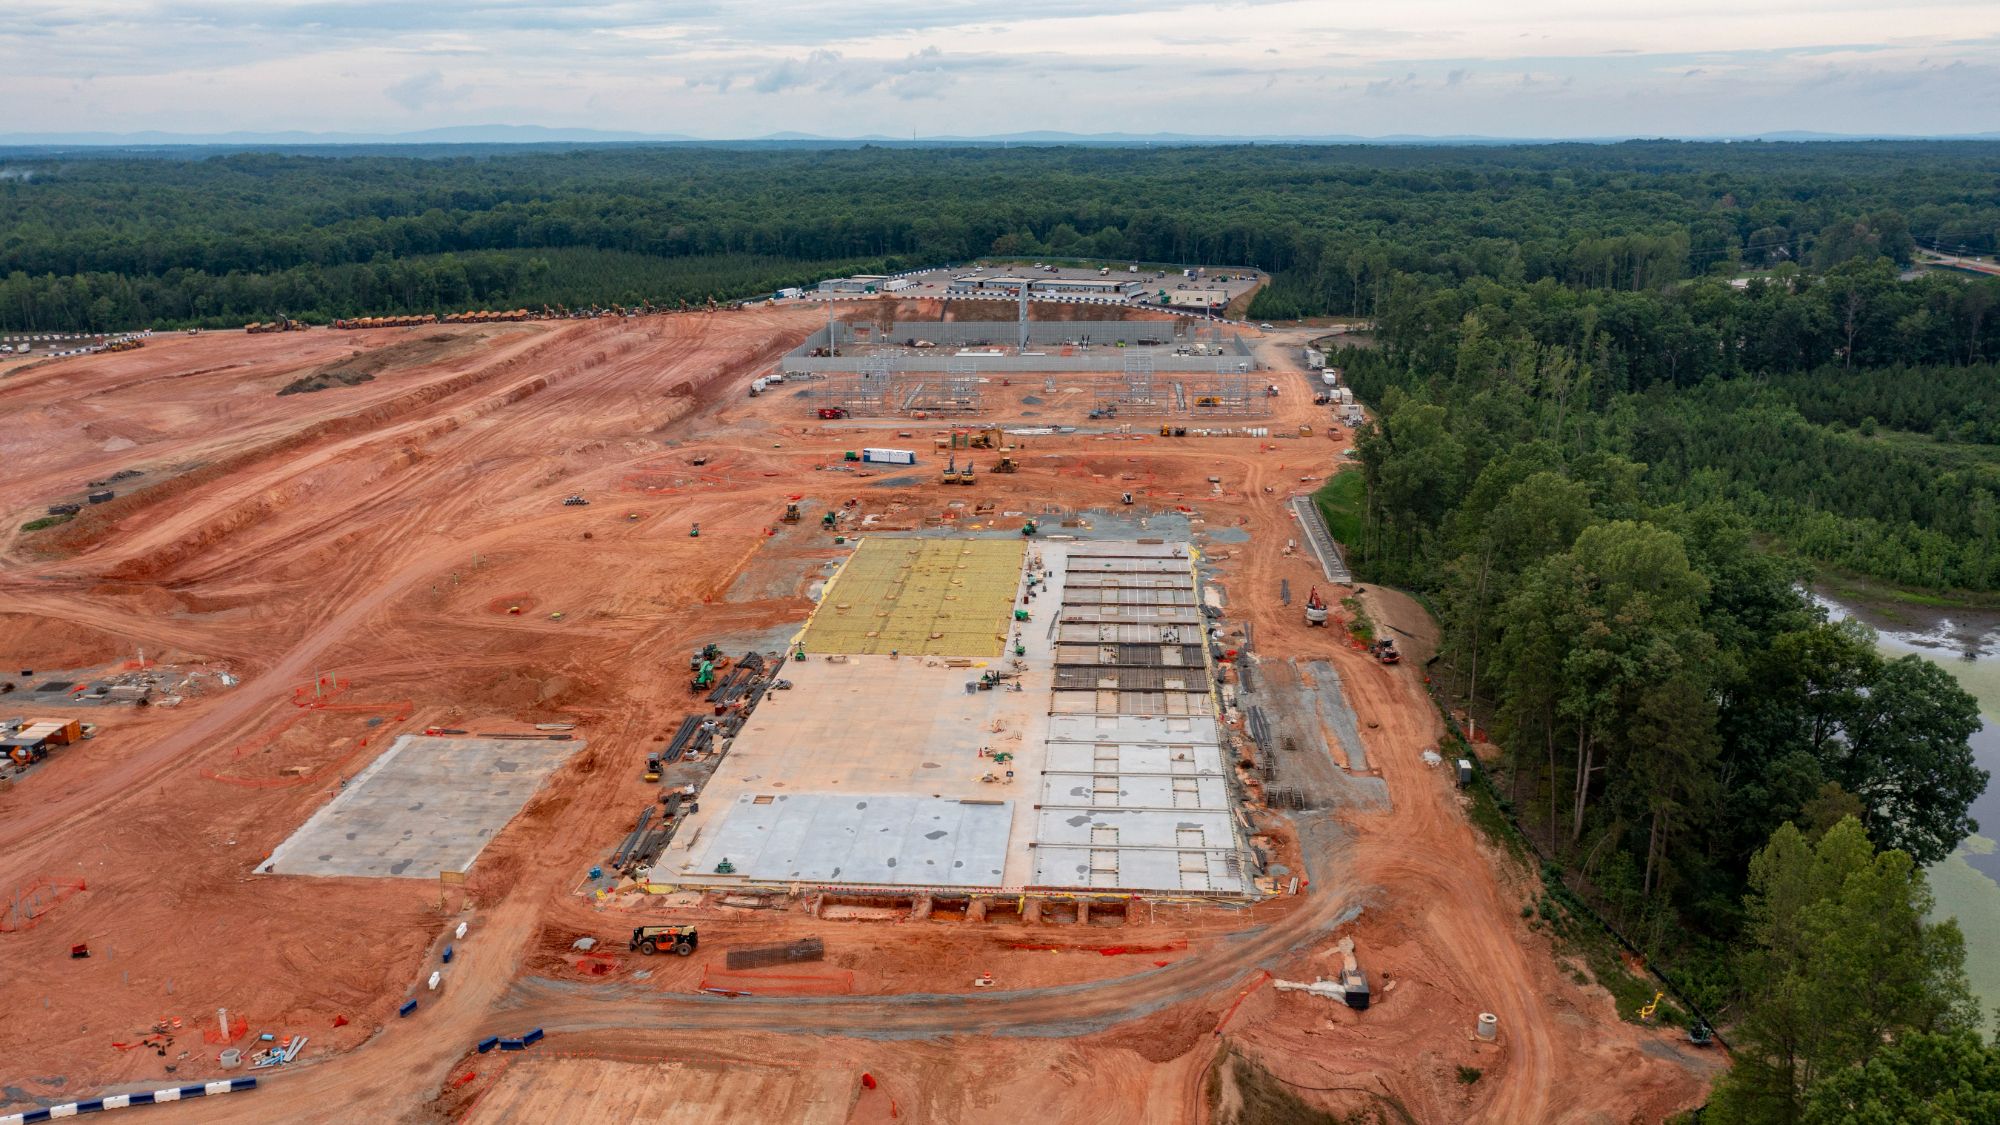
Z.ai powers up a 1-gigawatt AI data center built entirely on Chinese chips, report claims — GLM developer now runs multiple 10,000-chip clusters with zero Nvidi

The source didn’t name the chip supplier, but Z.ai’s recent training history points to Huawei. The company released GLM-5.2 in June , an open-weight model purportedly trained entirely on Huawei Ascend accelerators with n…

Jensen Huang argues American companies should be allowed to use Chinese AI models — Nvidia CEO says backdoors connected to China are misconceptions

One of the biggest concerns of U.S. leaders have is that these AI models might come with vulnerabilities that the Chinese government can use to attack American interests, but Huang said that this is an incorrect assumpti…