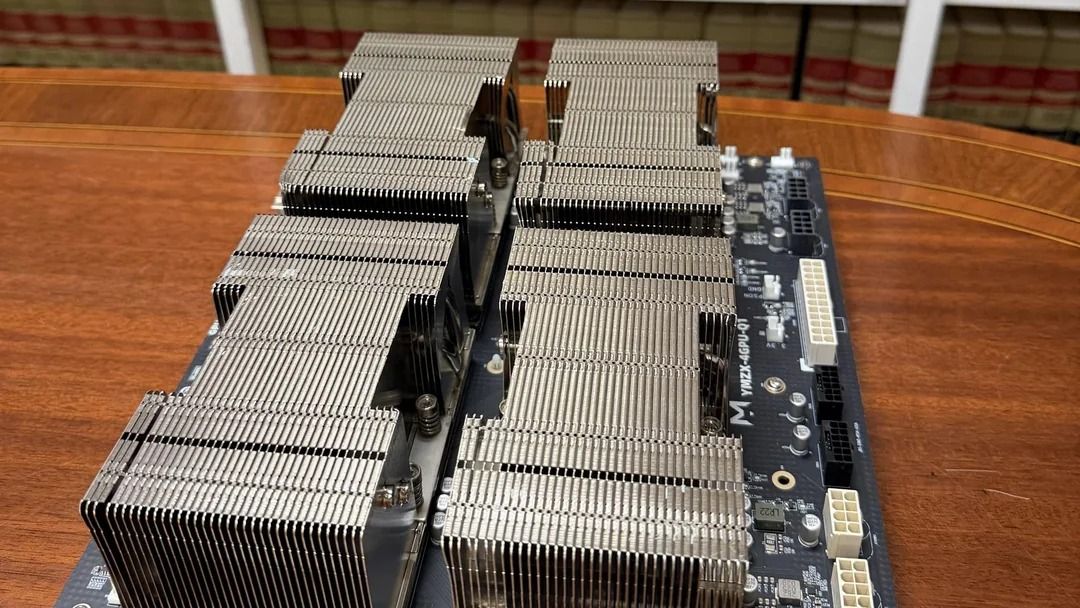
The resets stopped after the builder capped the clocks and removed one board whose power connector had a burn mark; “Check your connectors, people.” Each card is now capped at 150 W, half of its 300 W rating, with the graphics clock capped at 1522 MHz. A 200 W cap brought no appreciable performance gains, according to tests.
The system memory hit uncorrected ECC errors, too, which went away after the builder dropped the RAM from DDR4-3200 to DDR4-2666. One GPU was connected at x4 instead of x8 at last check, and the builder plans to reseat it; one commenter traced the same kind of problem on their own V100 to a bad cable.
The pain was worth the payoff as an estimated 50–60% of the lawyer’s existing LLM workflows can now run on the box instead of frontier models. Helping bridge the gap is a second DeepSeek server on two DGX Sparks , where the two systems hand work off to each other. The setup does appear to save money, at least when compared to API pricing , although the builder says it’s not really faster. However, it will protect client data “once it is self contained, which is the goal.”
The builder added that the V100 box might also get a 240 V circuit. Beyond power, the system is also on borrowed time with the Nvidia R580 driver branch, which is the last to support Volta . For now, the lawyer admits that it’s mostly a hobby, but in the future it may be a business idea. The next step is to handle two or three requests at once, something built and checked on a test system but not yet on the server.
Follow Tom’s Hardware on Google News , or add us as a preferred source , to get our latest news, analysis, & reviews in your feeds.
Shane Downing Social Links Navigation Contributing Writer Shane Downing is a Contributing Writer for Tom’s Hardware, covering consumer storage, PC hardware, and AI.
acadia11 2 bit quantinization , I’m shocked it’s useful, very. I’d expect it to not be very good? Reply
hwertz acadia11 said: 2 bit quantinization , I’m shocked it’s useful, very. I’d expect it to not be very good? Yeah I found models to rapidly get 'stupider' below Q4 and I haven't bothered with below Q6_KM (which averages about 4.5 by using higher quant on 'important' parts and lower on others.) But, I suppose for just pulling names, dates, and events, that's a relatively easy task. Reply
marmarmar34 hwertz said: Yeah I found models to rapidly get 'stupider' below Q4 and I haven't bothered with below Q6_KM (which averages about 4.5 by using higher quant on 'important' parts and lower on others.) But, I suppose for just pulling names, dates, and events, that's a relatively easy task. If that's all it's doing, wouldn't it just make significantly more sense to use any databasing software at a fraction of the cost? Seems like a huge waste if that's all they are doing… Reply
ProprietaryLegalAI acadia11 said: 2 bit quantinization , I’m shocked it’s useful, very. I’d expect it to not be very good? I am the lawyer in question. The github repo has topk accuracuy measures. With an effective harness (something I have been working on for many months), the quant does useful work. I am in the process of finalizing an alternative build that runs NVFP4 (essentially full precision) on the same hardware. Hoping to still get 80 tok/s on legal and prose, which is very useable. Reply
ProprietaryLegalAI marmarmar34 said: If that's all it's doing, wouldn't it just make significantly more sense to use any databasing software at a fraction of the cost? Seems like a huge waste if that's all they are doing… (I am the lawyer, again). I am working towards a fully offline local setup, which will likely wind up having significant value for regulated professions, legal or otherwise. In the interim, the goal is to slice off frontier tokens where possible. Also, getting this hardware working has been a fun hobby. Reply
palladin9479 This is the ultimate destination for AI type workloads. Keeps data from being mined by the hyperscalers who then sell you advertising. Reply
ProprietaryLegalAI Admin said: A lawyer runs DeepSeek V4.1 Flash on eight used 2018-era Nvidia V100 GPUs at up to 215 tokens/s, keeping case files in the office. Lawyer builds private AI server with eight used Nvidia V100 GPUs : Read more I am the lawyer in question. Info about the build and about me are below. I am a full time civil litigation attorney, but I now also do LLM consulting. https://github.com/ProprietaryLegal/Volta-sPLIt-DeepSeek-V4.1-Flash-1017-8xV100-SXM2-PP2xTP4 https://proprietarylegal.ai https://x.com/NicoTheGreco https://www.linkedin.com/in/nicholasmermiges/ Reply
kealii123 ProprietaryLegalAI said: I am the lawyer in question. Info about the build and about me are below. I am a full time civil litigation attorney, but I now also do LLM consulting. https://github.com/ProprietaryLegal/Volta-sPLIt-DeepSeek-V4.1-Flash-1017-8xV100-SXM2-PP2xTP4 https://proprietarylegal.ai https://x.com/NicoTheGreco https://www.linkedin.com/in/nicholasmermiges/ This is the coolest thing I've ever read on this site. Well done! I bet the value and experience this has given you for consulting is the best thing about the whole adventure. Reply
phead128 My company (Fortune 500) software engineers is also building a local data server to run open weights while at same time getting Claude enterprise. They cite high API token cost for Claude as reason for building a local data server to run open weights. Quite frankly, any company who doesn’t adopt open weights to supplement Opus models will be non-competitive in future. The amount of token costs you can save is not trivial. If you can get almost unlimited tokens on SOTA models, it would be very attractive. Reply
Key considerations
- Investor positioning can change fast
- Volatility remains possible near catalysts
- Macro rates and liquidity can dominate flows
Reference reading
- https://www.tomshardware.com/tech-industry/artificial-intelligence/SPONSORED_LINK_URL
- https://www.tomshardware.com/tech-industry/artificial-intelligence/lawyer-builds-private-ai-server-with-eight-used-nvidia-v100-gpus-up-to-215-tokens-per-second-to-keep-legal-files-offline-costing-about-usd2-400-per-four-gpu-board#main
- https://futureplc.com/privacy-policy/
- How AI Is Changing the Pace of Discovery for Millions Living With Dementia
- Nvidia released its 8800 GTX GPU 20 years ago today, celebrates with Steam game homage
- Security researcher had to jailbreak their car just to update the clock
- Synaptics sends cease-and-desist order to creator of open-source DisplayLink driver, dares him to publicize its threats
- More Performance From Every Byte: How Full-Stack Codesign Solves AI’s Memory Challenge
Informational only. No financial advice. Do your own research.