Hot Chips 2026: Nvidia presents Groq 3 LPX architecture and unveils its first third-party inference benchmark
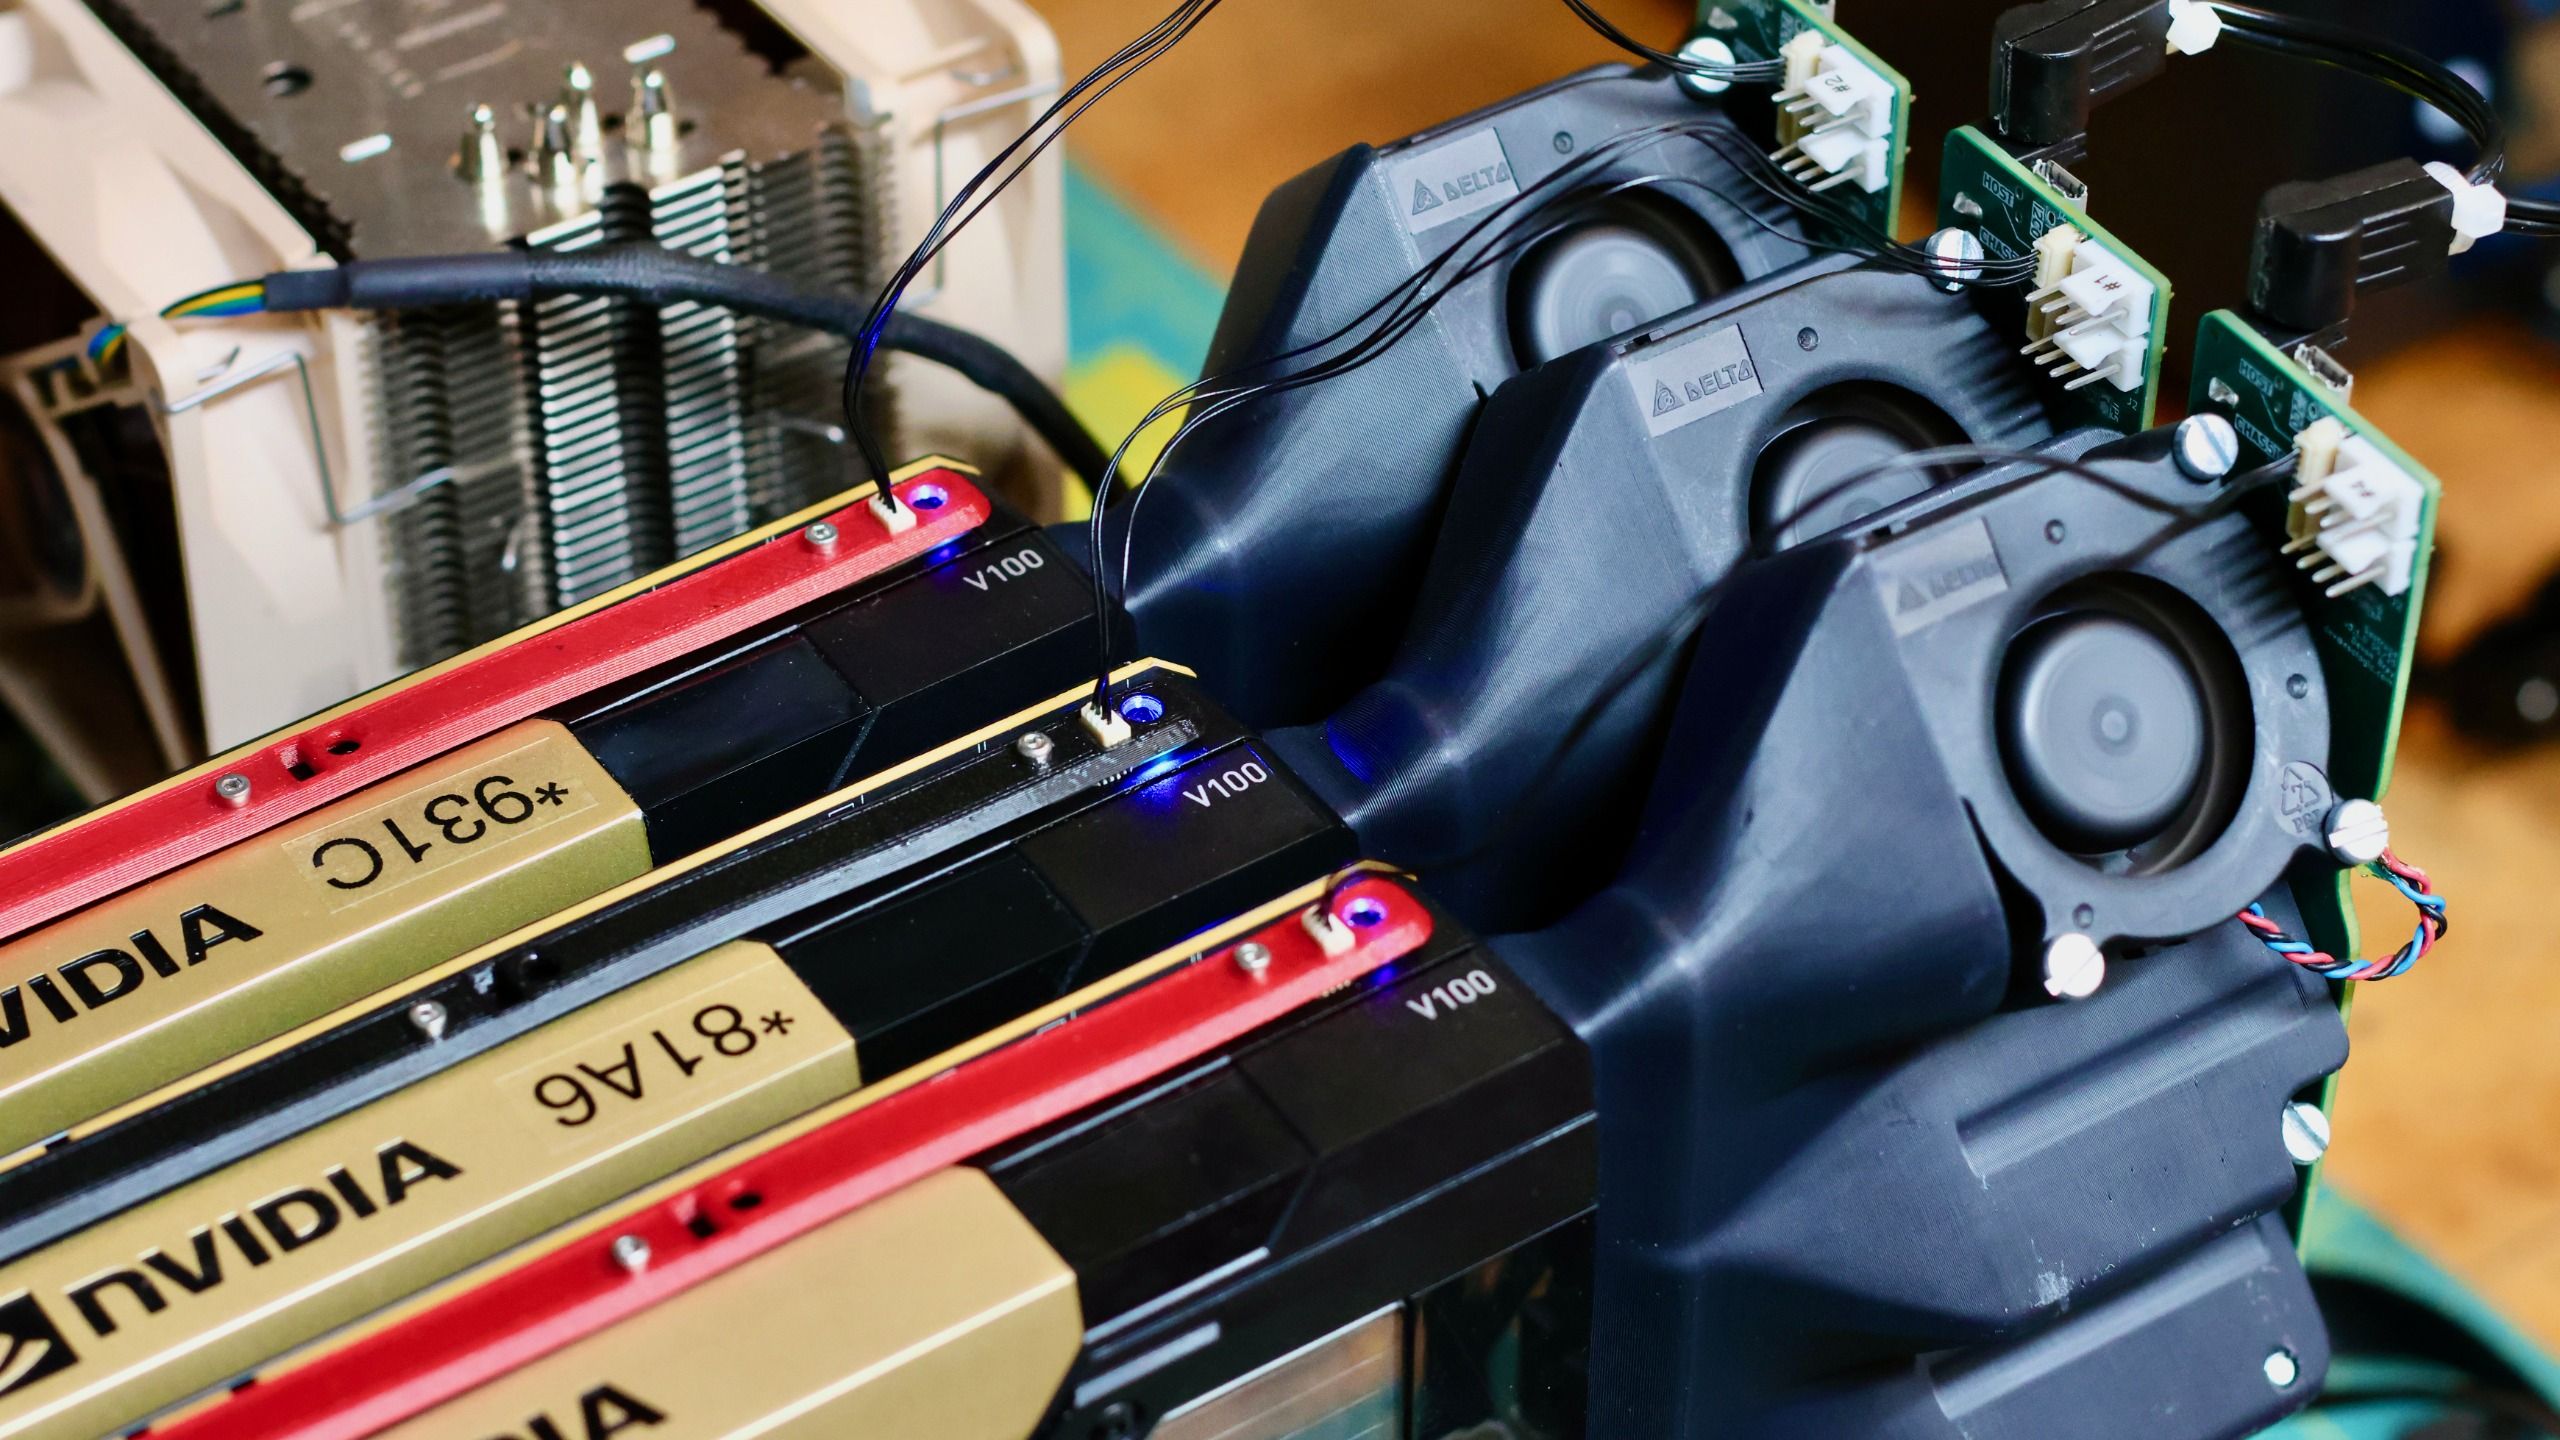
The Mac comparison comes from the oMLX benchmark page for the M5 Max with 40 GPU cores and 128GB of unified memory, and that hits 43.9 tokens per second with a ~195K-token prompt on the Qwen 3.6 35B model. The Mac is slightly ahead at 4K and 32K, while the V100s pull ahead at 64K and 128K, by 19% at the longest context. These numbers have to be taken loosely, as the machines use different runtimes.
The Spark run came from Kleybrink’s dgx-spark-bench, using Ollama in thinking mode with short prompts. Its 45.8 tokens per second is less than half the V100s’ 4K figure.
Going further to modern GPUs, which “destroy our decommissioned equivalents,” as the builder puts it, you get about 315 tokens per second on two H100s and about 455 on one B200 at 128K, the B200 roughly six times the V100 box, even though the hosted cards ran the full 16-bit model against the V100s’ 8-bit. Parasail, an inference provider, sponsored that comparison with dedicated H100 and B200 deployments.
As for energy, the V100 setup came out to about 0.02 kWh for a 128K 35B run, with the P100s taking twice that much and two or three K80s as much as 0.35 to 0.45 kWh. The V100-16GB simply “[puts] up better scores while consuming less energy,” in comparison to the P100s. These numbers are for the GPUs and not from the wall.
There’s more to come. The builder wants a benchmark that “maps to ‘software factory’ performance,” a term for models being prompted constantly, around the clock, where instant speed matters less. Then there’s the cooler, which is “almost ready for release,” with beta testers to be recruited from the mailing list, although no date has been given. From the Reddit thread, the builder mentions the intention to compare inference backends and use speculative decoding to improve performance.
Follow Tom’s Hardware on Google News , or add us as a preferred source , to get our latest news, analysis, & reviews in your feeds.
Shane Downing Social Links Navigation Contributing Writer Shane Downing is a Contributing Writer for Tom’s Hardware, covering consumer storage, PC hardware, and AI.
Arkitekt78 Its almost as if if these engineers knew what they were doing, they wouldn't have to be spending billions of $ on "the best" and we wouldn't be in a RAM/storage/GPU crisis. Huh. Reply
Rand0m_Guy So it can do 86,400 tokens per day… Congrats, your rig is useless in the first 5mins of my work! but lets do the math, this rig is worth $1042, you would need 96 of these rigs to sustain my daily (8-hour) load, bringing the total to $100,032 per DAY, vs my roughly $5K per month I pay now. Youre right, this rig is e-waste, aka garbage! Reply
mangaba Rand0m_Guy said: So it can do 86,400 tokens per day… Congrats, your rig is useless in the first 5mins of my work! but lets do the math, this rig is worth $1042, you would need 96 of these rigs to sustain my daily (8-hour) load, bringing the total to $100,032 per DAY, vs my roughly $5K per month I pay now. Youre right, this rig is e-waste, aka garbage! Humm, now I know why you use a lot o IA: e-waste rig -100 token/sec*86400 sec/day = 8.640.000 tokens/day. You are wasting $4000 by month… your brain is already shrinking Reply
helper800 Arkitekt78 said: Its almost as if if these engineers knew what they were doing, they wouldn't have to be spending billions of $ on "the best" and we wouldn't be in a RAM/storage/GPU crisis. Huh. The problem was, and continues to be, density and supply, not money. Because that was the issue, large companies would not have seeked out older tech that takes up 5 times the space for the same speed at 1/5th the efficiency to fill their needs. Money was never the constraint. Reply
Dav_Daddy Where are the numbers for the K80's? I was thinking about grabbing a couple of them while they are still cheap but was afraid they'd be too slow. Assuming you're a single user and you are just using them for chat/coding anything much above 35 tok/sec is unnecessary. Sure generating a response takes a few seconds but on the bright side you can monitor the thing and stop it if it gets into a loop or something. Reply
helper800 mangaba said: Humm, now I know why you use a lot o IA: e-waste rig -100 token/sec*86400 sec/day = 8.640.000 tokens/day. You are wasting $4000 by month… your brain is already shrinking Hey, maybe you saved them 4k a month after they get an older 1000-2000 dollar system for their work 'needs.' Reply
helper800 Dav_Daddy said: Where are the numbers for the K80's? I was thinking about grabbing a couple of them while they are still cheap but was afraid they'd be too slow. Assuming you're a single user and you are just using them for chat/coding anything much above 35 tok/sec is unnecessary. Sure generating a response takes a few seconds but on the bright side you can monitor the thing and stop it if it gets into a loop or something. I asked AI how many tokens a K80 would get with Qwen 3.6 with 35B parameters, and it said the following regarding K80s, "…getting Qwen 3.6 running at these speeds requires custom/patched engines or sm_37 builds, and splitting layers across dies or host RAM adds PCIe/bridge overhead." It also estimated that one of them would do between 10-30 tokens a second depending upon parameters, context length, quant, and speculative decoding with Qwen. K80's also have two GPUs and each one has only half the cards 24gb of memory available to it. Reply
Key considerations
- Investor positioning can change fast
- Volatility remains possible near catalysts
- Macro rates and liquidity can dominate flows
Reference reading
- https://www.tomshardware.com/tech-industry/artificial-intelligence/SPONSORED_LINK_URL
- https://www.tomshardware.com/tech-industry/artificial-intelligence/three-e-waste-nvidia-v100s-hit-100-tokens-per-second-on-qwen-3-6-35b-in-a-usd1-042-homelab-rig-decommissioned-gpus-outpace-a-usd5-399-m5-max-mac-studio-at-long-contexts#main
- https://futureplc.com/terms-conditions/
- Voyager 1 spacecraft crosses milestones distance of one-light day from Earth 49 years after launch
- Developer vibe codes Windows 11 alternative operating system for amd64, arm64, and riscv64 hardware
- Elon Musk’s SpaceXAI suffers chemical spill at Mississippi AI data center
- Voyager 1 spacecraft crosses milestones distance of one-light day from Earth 49 years after launch
- A New Dawn in the Cloud: ‘Warhammer 40,000: Dawn of War IV’ Is Coming to GeForce NOW
Informational only. No financial advice. Do your own research.